
There’s a specific kind of meeting nobody warns you about. You’ve built your first agent, you’re demoing it to leadership, and someone asks a question slightly off from what you tested. The agent answers. Confidently. Completely wrong. And you watch the room’s enthusiasm for your whole AI program cool by about ten degrees in real time.
That meeting is what this article is trying to help you avoid.
Most people start with the wrong question. They ask “how do I build an agent” months before they’ve answered the harder one: which agent, and why that one first. And the stakes on that question just went up. With the Winter ‘27 release, Agentforce will be switched on by default across eligible editions, rather than left as something you opt into, with rolling enablement that began in early September 2026. The capability is going to be sitting in your org whether you’ve scoped anything or not. So the real work now is picking a first use case that earns you a second round instead of ending the conversation.
Key Takeaways
- The first use case fails on scope, not on technology. Too broad, too public, or built on ungoverned data.
- Score candidates on blast radius, read-vs-write, data surface, volume, escalation, and a written success metric. Low scores win.
- Start internal and read-only. Climb toward customer-facing and write actions as trust builds.
- Define “resolved” before you launch, because that number will get questioned.
- Keep shrinking the use case until its worst possible output is boring.
Table of Contents
Why Most First Agentforce Use Cases Fail (And It’s Not the Tech)
Below is an uncomfortable truth: when first use cases fail, the model is usually fine. The scoping was wrong.
Gartner predicts that over 40% of agentic AI projects will be canceled by the end of 2027, pointing to escalating costs, unclear business value, and weak risk controls. Separately, Gartner expects organizations to abandon 60% of AI projects that lack AI-ready data through 2026. Read those two lists of reasons again. “The AI wasn’t smart enough” isn’t on either list.
You’ll also see the MIT NANDA report that 95% of enterprise GenAI pilots delivered no measurable return thrown around. Worth knowing, but worth reading carefully too: that number measures profit-and-loss impact, not whether the thing technically worked. It’s a signal about business value, not a verdict on the technology.
The real failure mode is a use case that is too broad, too high-stakes, or quietly dependent on data nobody actually governs. All three are scoping problems. All three are fixable before you build a single thing.
What a “Won’t Embarrass You” Use Case Actually Looks Like
Narrow enough to clean up
One job. One group of users. One source of data. That’s it.
Salesforce’s own Trailhead planning module walks through a hotel example where the first version of a reservation agent can only look up reservation details and resend confirmation emails. Everything else goes to a human. And in that same Trailhead unit on identifying the agent use case, the team deliberately excluded the FAQ use case they wanted. Because the knowledge articles were inconsistently formatted, outdated, and even contradicted one another. They shrank the scope instead of pushing through. Good instinct.
Low-risk enough to survive a mistake
Your first agent will get things wrong. Plan for it being allowed to.
Salesforce’s 2026 survey of 2,025 agentic AI leaders found that clean, accessible data and a tightly bounded use case tied for the top two success factors, each cited by 36% of respondents. The study also revealed an important insight often missed in the rush: being first to launch doesn’t necessarily guarantee the fastest ROI (return on investment). In this context, ‘scope’ matters more than speed.
Visible enough to earn round two
Even a ‘safe’ pilot project must demonstrate its effectiveness; otherwise, it won’t secure the next round of investment. Projects that are ‘highly visible’ are not the same as those that represent ‘big bets. When Salesforce rolled out its own help-site agent, it started with just 200 authenticated users over a four-week window before scaling. Small, watched, measured. Then bigger.
The Embarrassment-Risk Scorecard
This is the part you can run against your backlog today. Six questions. For each one, a lower score means a safer first pick. If a candidate use case scores high across the board, it’s not your first agent — it might be your third.
| # | Question | Red flag (high risk) | Safe (low risk) |
|---|---|---|---|
| 1 | Blast radius — who sees the worst answer? | Customers, in public | Internal staff only |
| 2 | Read vs. write — can it change records? | Issues refunds, edits cases | Read-only lookups |
| 3 | Data surface — what can its user see? | Ungoverned objects | One clean, governed source |
| 4 | Volume — is it worth automating? | Rare, one-off tasks | High-frequency, repeatable |
| 5 | Escalation — is there a human? | No handoff defined | Handoff built before launch |
| 6 | Measurable — did you define success? | “We’ll figure it out” | KPI written down first |
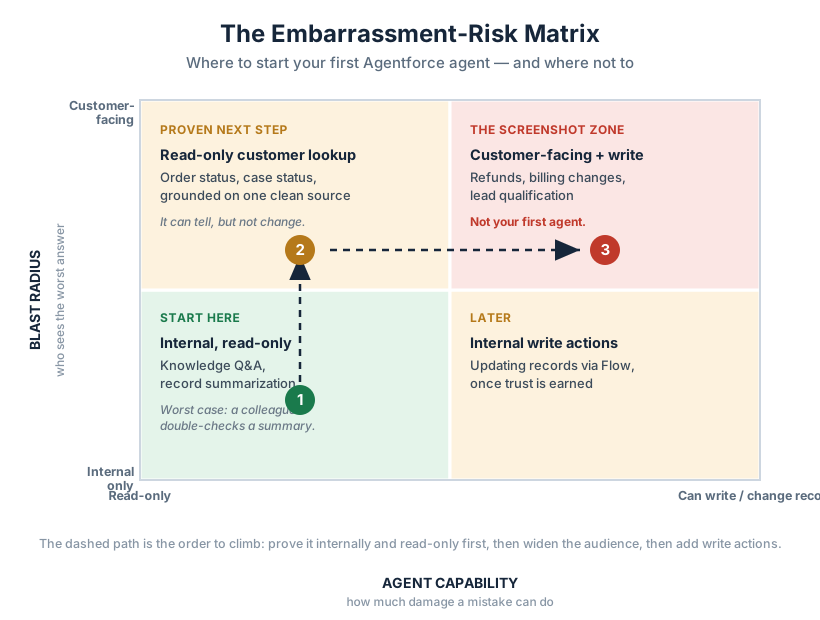
A few of these deserve more than a table row.
Blast radius is the one people underweight. An internal summarizer that hallucinates costs someone a minute of double-checking. A customer-facing agent that does the same thing becomes a screenshot. Same error, wildly different consequences.
Data surface is the trap nobody sees coming. In Agentforce, a service agent runs as a single designated user, which means whatever that user can access is what a customer can be told. So scoping the agent’s data access isn’t a technical nicety; it’s a safety control. Point an agent at objects nobody governs, and you’ve built a very fast way to surface your messiest records to the outside world.
Measurable success sounds obvious until you try to define “resolved.” Salesforce’s own help-site agent has reported resolution rates anywhere from 63% to 85% depending on whether abandoned conversations count. If a definition can swing that much for the company that built the product, a skeptical stakeholder can swing yours too. Write down what “success” means before you build, not after someone questions the number.
The Scoping Traps That Kill Pilots Quietly
Confusing “impressive” with “winnable”
Often, leadership selects the worst possible first ‘use case,’ choosing it simply because it looks impressive. Gently point out to them that opting for something ‘boring but highly reliable’ is what earns you the mandate to pursue more ambitious work later on. A pilot project that quietly and effectively delivers results paves the way for the next three projects. Conversely, a flashy project that stumbles can end the entire program.
Underestimating the data surface
Teams scope the task and forget the data the task touches. An agent that “answers account questions” is quietly reaching into fields, related records, and knowledge articles you may not have looked at in a year.
Salesforce has clearly stated that messy data is the single biggest reason agents fail. And in that 2026 leaders survey, only 31% of organizations had fully unified their relevant data before launching. Most are grounding agents on data they haven’t actually audited. Don’t be most.
Picking a job that Flow should do
Not every repetitive task wants an AI agent. If the process is static and the rules never change, that’s a Flow. Salesforce’s own guidance draws the line clearly: Agentforce earns its place when a job needs interpretation, summarization, or context, and a deterministic process belongs in Flow Builder instead. The same post has a line I keep coming back to: if your data is a mess, an agent “would only summarize the confusion faster.”
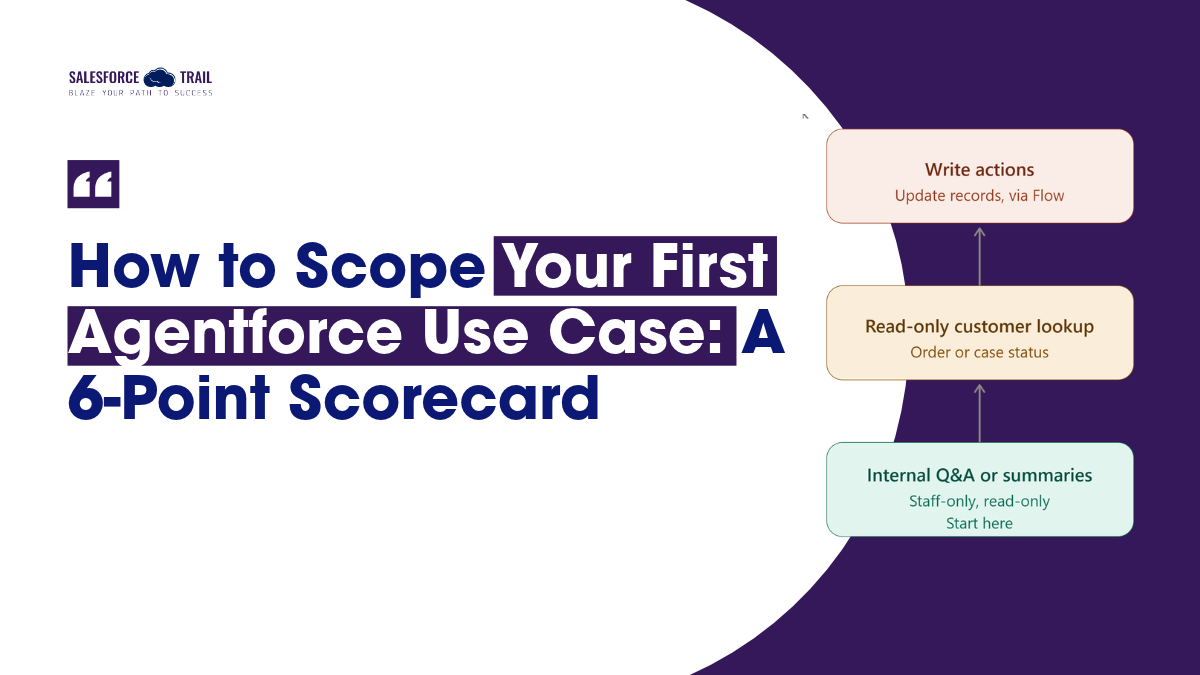
A Safe Starter Ladder (Where I’d Actually Begin)
If you handed me a backlog and asked where to start, I’d tackle the lowest risk first.
- Internal knowledge Q&A or record summarization. Staff-only, read-only. The agent summarizes a case history or answers an internal policy question. If it’s wrong, a colleague catches it, and nobody outside the building ever knows.
- Read-only customer lookup. Order status, case status, grounded in one clean knowledge source. Customer-facing, but it can only tell, not change. This is where Wiley started with its first service agent, and Salesforce reports it drove a 40%+ increase in case resolution over its previous bot during its back-to-school rush. Worth noting the baseline there is the old chatbot, not human agents.
- Write actions, added later. Updating records, issuing something, triggering a process — usually through Flow, once the agent has earned trust on the read-only work.
One nudge in the other direction: a lot of people want their first agent to qualify inbound leads. I’d hold off. That touches prospects and revenue directly, which puts the blast radius high before you’ve proven anything. For reference, 1-800Accountant leaned on Agentforce for tax-season support, and Salesforce reports it resolving up to 50% of inquiries, though the exact figure shifts across Salesforce’s own materials, so treat it as a directional win, not a promise.
Run the Scorecard Against Your Own Backlog
Let’s make it concrete. Say the backlog item is “an agent that answers billing questions for customers.”
Run it through the six questions. Blast radius: customer-facing, public. Read vs. write: billing answers can touch sensitive balances. Data surface: billing objects, which are rarely the cleanest or best-governed in an org. That’s three high-risk scores before we’ve even reached volume. This isn’t a first use case. It’s a fourth one.
Now narrow it. “Summarize a customer’s last three cases for the support rep, internal-only.” Watch what happens. Blast radius drops to internal. It’s read-only. The data surface shrinks to the Case object your support team already lives in. Same underlying capability, completely different risk profile. That second version is a first agent. The first version is a cautionary tale waiting to happen.
That’s the whole exercise. Take the thing you were excited to build, and keep shrinking it until every score is low.
How You’ll Know It’s Time for Version Two
Graduating is a decision, not a feeling. Move to a wider scope when three things hold: your success metric is stable and you actually trust it, your escalation rate is trending down, and the data you’re grounding on hasn’t sprung any leaks. Then you widen the audience, add write actions, or point it at a second data source.
This is also the moment the real homework starts. You can’t scope your data cleanup until you’ve scoped your use case, because the use case tells you exactly which objects and fields need to be clean. First you pick the job. Then you get the org ready for it.
Frequently Asked Questions
A narrow, high-volume task that reads from one clean data source and has a human to escalate to. Internal knowledge Q&A or record summarization is a strong starting point because mistakes stay inside the building and the agent only reads data, never changes it.
It should do one clearly defined job for one group of users, ideally looking something up and answering rather than taking action on records. Salesforce’s own planning guidance recommends scoping the smallest unit of work that still delivers real value.
If the task needs interpretation, summarization, or context, it’s a fit for Agentforce. If the process is static with fixed rules that never change, Salesforce recommends building it in Flow instead. An agent on a deterministic process is overkill.
With Flex Credits, a standard action costs about $0.10, and customers on Enterprise Edition or above can get 100,000 credits at no cost through Salesforce Foundations. A tightly scoped pilot is inexpensive. The real risk of a first agent is reputational, not financial.
Usually because of scope and data, not the model. Gartner attributes agentic AI cancellations to unclear business value, rising costs, and weak risk controls — and separately flags lack of AI-ready data as a major cause of abandonment.
Internal is the safer place to start. A staff-only agent that makes a mistake costs someone a minute of double-checking. A customer-facing one making the same mistake becomes a public screenshot. Prove it internally, then take it outside.
- Akanksha Shukla
- Akanksha Shukla